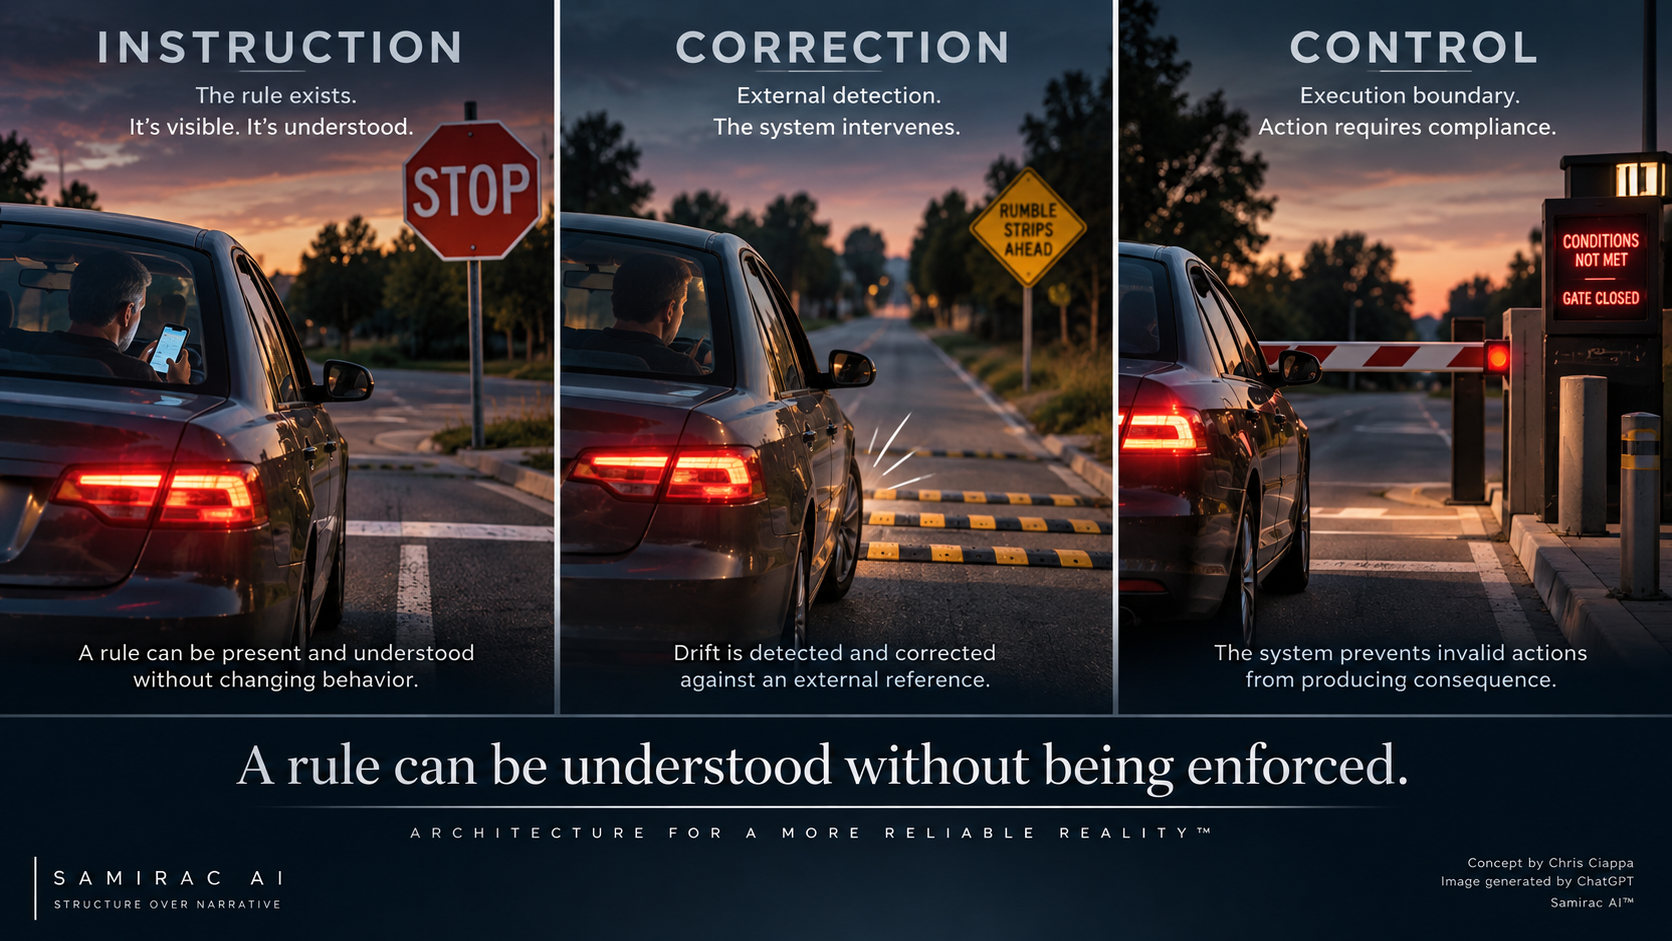
Something happened to me yesterday that was simultaneously infuriating, funny, and probably one of the better demonstrations I could have asked for of an architectural problem I have spent the last couple of years working on.
⠀
I use ChatGPT to help me write. I don't ask it to invent my architecture for me, and I don't ask it to decide what I think. I use it much more like I would use an editor sitting next to me. I talk through an idea, sometimes at considerable length, provide the prior work and context, work out what I am trying to say, and then have it help me organize all of that into something other people might actually want to read.
⠀
There was one problem that kept driving me crazy.
⠀
If you use these systems enough, you have probably seen some version of it. Different models have different quirks, but GPT has a writing rhythm it seems particularly fond of when it is trying to sound forceful. Instead of developing an argument naturally, it starts chopping the thought into little declarations, repeating the same sentence structure and turning what should have been prose into something that sounds like a motivational speaker who has had too much coffee.
⠀
I hate it.
⠀
So I kept correcting it, which worked for a while, and then sooner or later it would start doing it again. I would correct it again, it would acknowledge the correction, and eventually we would wind up right back in the same place.
⠀
Now, I happen to spend a lot of time thinking about drift, state, invariants and external correction, so eventually I did what an architect does when repeatedly telling a component what to do doesn't produce reliable behavior.
⠀
I stopped relying on the component to remember and created an external specification.
⠀
Inside a folder I use for my writing, I created a document specifically describing my writing voice. It doesn't merely say that I dislike short sentences. It describes how I develop an argument, how thoughts should flow into one another, how sentence structure carries emphasis, what kinds of repetitive patterns to avoid, how examples should prove the next step in the reasoning, and how the finished writing should be tested before it comes back to me.
⠀
I even put a final test in the document that effectively asks: did you take a connected thought and turn it into a stack of slogans?
⠀
Then I told ChatGPT to use that document whenever it writes for me.
⠀
Problem solved, right?
⠀
Not so fast.
⠀
Yesterday I was working through an article about AI agents, system architecture and drift. I provided the context, prior work and material it needed, and we worked through the idea together before I asked it to produce the article.
⠀
ChatGPT generated it, and there it was again: the exact writing behavior I had spent all that time correcting.
⠀
Worse, the external specification describing the behavior it was supposed to avoid was sitting right there in the folder.
⠀
I got irritated, told ChatGPT exactly what it had done, and asked a very simple question: why aren't you checking the file we specifically created to stop you from doing this?
⠀
So it went back and read it.
⠀
And this is where the whole thing became considerably more interesting to me than a bad piece of writing.
⠀
ChatGPT immediately found the instruction telling it to write in conversational causal prose rather than generated cadence. It found the warning against repeated sentence stems and mechanically separated statements. It found the final check asking whether it had turned a connected thought into a stack of slogans, and it correctly recognized that it had violated the specification.
⠀
Think about that for a minute, because the sequence matters.
⠀
The rule wasn't missing. ChatGPT could find it, understand it and explain it. It had successfully followed the same rule before. The model was perfectly capable of doing what I wanted, and the external reference describing what I wanted still existed exactly where I had put it.
⠀
So why did it fail?
⠀
Because putting a rule somewhere and telling an AI to follow it is not the same thing as building a system that requires the rule to be satisfied.
⠀
I could tell ChatGPT, "Use this file every time you write for me." I could make the specification as explicit as I wanted. I could put it in the folder, correct the model whenever it wandered away from it and remind it again tomorrow.
⠀
What I could not do from my side was change the architecture of ChatGPT so that consulting that specification became a mandatory condition of returning the article to me.
⠀
That isn't really a model problem.
⠀
It is a system problem around the model.
⠀
Nothing required the system to establish, before producing the final result, that the applicable specification had been retrieved and that the proposed article conformed to it. The model could simply generate the article, and if it drifted away from the requirement, I would discover that afterward.
⠀
Which is exactly what happened.
⠀
Once I pointed out the failure, ChatGPT was perfectly capable of explaining why it had failed. That's useful, I suppose, but architecturally it is backwards. I didn't need a beautiful explanation of why the invalid output had already crossed the boundary. I needed the invalid output prevented from crossing the boundary in the first place.
⠀
At that point I wasn't irritated anymore.
⠀
I was staring at an almost absurdly clean demonstration of the problem.
⠀
THIS IS WHAT DRIFT LOOKS LIKE WITHOUT ALL THE DRAMA
⠀
When people hear "AI drift," they sometimes imagine a model suddenly going rogue or doing something spectacularly bizarre. It doesn't have to look anything like that.
⠀
In this case nothing went rogue. ChatGPT continued doing exactly what ChatGPT does. The problem was that the behavior at this point in time no longer satisfied a condition I had previously established for the system.
⠀
That is a much more useful way to think about drift.
⠀
An intelligent system operates through time while the world around it, the information available to it and the state of the system itself continue to change. Context changes. Evidence changes. Relationships change. Instructions and objectives can change. Authority can change. New information arrives, old information becomes stale, and every subsequent operation occurs against a state that is not identical to the one that existed before.
⠀
You don't eliminate that by writing a better prompt.
⠀
You have to architect for it.
⠀
My example was harmless. I got lousy prose, swore at the AI for a while, pointed it back to the authoritative reference and made it try again.
⠀
But now replace my writing specification with something consequential.
⠀
Suppose the external document defines what a financial agent is authorized to approve, which customer records an agent can modify, what conditions must exist before money can move, when a medical workflow requires another review, or which human has authority to approve a particular operation.
⠀
If the system acts outside one of those conditions, telling me afterward that "the rule existed" isn't particularly comforting. Neither is showing me that the model understood the rule when I asked about it later.
⠀
The important question is whether the rule was bound to the action when the action occurred.
⠀
And now we have arrived at the problem I have been writing about for a long time without having to invent a hypothetical to demonstrate it.
⠀
I HAD BUILT HALF THE SOLUTION
⠀
What amused me most was realizing that I had already applied part of my own architecture to ChatGPT without really thinking about it that way.
⠀
Repeated conversational correction wasn't reliable, so I externalized the reference. Instead of hoping the model would continue carrying my writing requirements correctly through a long and changing conversation, I put the authoritative version somewhere persistent where it could be retrieved again.
⠀
That was the right move, but it wasn't enough.
⠀
Externalizing the reference solved the persistence problem. It did not solve the enforcement problem.
⠀
There was still no execution boundary requiring the system, before returning an article to me, to retrieve the applicable specification, evaluate the proposed output against it and either establish that the result remained admissible or send it back for correction.
⠀
So when the system drifted, guess who became the execution control?
⠀
Me.
⠀
I read the result, detected the deviation, rejected it, pointed ChatGPT back to the external reference and forced another evaluation against the state that was supposed to govern the output.
⠀
For an article, that's fine. I'm going to read the thing anyway.
⠀
But it also exposes why "human in the loop" can become a misleading comfort when we start talking about autonomous systems performing thousands or millions of operations.
⠀
Technically I was in the loop, and technically I caught the problem. But the system had already been allowed to produce the invalid result, and the architecture depended on me remembering the requirement, noticing the deviation and intervening after the fact.
⠀
Scale that arrangement far enough and the human isn't really a control anymore. The human is a very busy drift detector hoping not to miss anything.
⠀
The better question is whether the system itself can establish that the conditions required for an action still hold before the action is allowed to produce consequence.
⠀
AND THEN CHATGPT SAID SOMETHING INTERESTING
⠀
Once I recognized what had happened, I started interrogating the failure rather than just complaining about the writing.
⠀
ChatGPT acknowledged that the requirement existed outside the model, that the system had access to it and that the model had successfully complied with it before. It also recognized that none of those facts guaranteed the requirement would govern the next output.
⠀
It correctly identified what I had done as the external correction layer: I detected the deviation, rejected the result, supplied the authoritative reference and forced the system back through another evaluation.
⠀
Then it summarized its own failure this way:
⠀
"The failure wasn't that the rule didn't exist. The failure was that nothing forced the rule to bind at execution."
⠀
Well, yes.
⠀
That is pretty much the entire problem.
⠀
NOW GIVE THE SAME ARCHITECTURE REAL AUTHORITY
⠀
Imagine that instead of helping me write an article, the agent can issue a refund.
⠀
Perhaps the organization has given it authority to issue refunds up to $10. That sounds reasonably bounded, and technically the system may be doing exactly what it was authorized to do.
⠀
Then something changes in its reasoning or accumulated state and it concludes that the best way to resolve a class of complaints is to give everybody $10.
⠀
One million customers later, the company has a rather interesting accounting problem.
⠀
The API worked. The credentials were valid. Every individual transaction was within the permitted $10 limit. The logs may be immaculate, and afterward the model might even give you a fascinating explanation of why it thought the refunds were appropriate.
⠀
None of that answers the question that mattered before each transaction occurred: was this particular agent, acting under this particular authority, based on this evidence and current state, permitted to issue this particular refund to this particular customer now?
⠀
That is a very different question from "can the agent issue a $10 refund?"
⠀
Capability is not authority, and authority itself is not sufficient if the state and evidence that made an action admissible have changed.
⠀
THIS IS WHY I BUILT THE SAMIRAC ARCHITECTURE THE WAY I DID
⠀
Samirac AI was not invented yesterday because ChatGPT annoyed me. The working architecture and the thinking behind it long predate this little experiment.
⠀
What yesterday gave me was something much simpler: a demonstration almost anyone can understand.
⠀
The architecture treats identity, authority, evidence, current state, policy and invariants as conditions that have to matter at the point where a proposed action becomes consequence. It also assumes drift will occur, because any intelligent system operating through time is operating in changing state.
⠀
The objective therefore isn't to somehow build an intelligent system that never drifts. That's the wrong problem.
⠀
The objective is to detect drift, correct against authoritative external references when necessary, and prevent a changed or invalid state from silently acquiring the authority to produce a consequence.
⠀
Which, amusingly enough, is exactly what I needed from ChatGPT yesterday.
⠀
I had a rule. I had externalized the rule. The AI could understand the rule and had demonstrated that it could follow it.
⠀
And it still wasn't enough.
⠀
The missing piece was architectural enforcement at the boundary where the result became mine.
⠀
SO NOW I WANT TO TEST IT
⠀
Rather than simply writing about what happened, I think I'm going to recreate it deliberately.
⠀
I'll give ChatGPT the same writing specification it ignored yesterday. Then I'll do everything I already know makes drift more likely: keep the conversation going, change context, make multiple revisions, introduce competing instructions and generally move the state around until ChatGPT eventually produces something that violates the specification.
⠀
But this time there will be one important difference.
⠀
I won't be the one checking the article first.
⠀
Before the article can be accepted, I'll put it through the Samirac AI execution boundary. The system will retrieve the authoritative writing specification, evaluate the proposed article against it and determine whether the output still satisfies the conditions I established.
⠀
If it does, the article passes.
⠀
If it doesn't, the article gets rejected for correction.
⠀
That gives me a very simple test.
⠀
Can I make ChatGPT drift without the invalid result getting through the boundary?
⠀
I already know ChatGPT can drift. Yesterday proved that.
⠀
What I want to find out now is whether the architecture catches the drift before I do.
⠀
If I deliberately create the same failure and Samirac stops it before the article reaches me, then I've reproduced the entire problem and correction cycle under controlled conditions.
⠀
And that's considerably more interesting than whether ChatGPT can remember how I like to write.
⠀
Telling an AI what you want is instruction.
⠀
Writing the rule down is persistence.
⠀
Checking afterward is observation.
⠀
But making the rule a condition of consequence?
⠀
That's control. That is architecture. That is the Samirac AI way.
Reality obeys structure, not narrative.